For high-throughput edge AI applications, the rate at which cameras capture images is often near the limit of latency tolerance. An automated system must be able to perform a wide variety of tasks, from tracking rapidly moving products on a conveyor belt to directing a robotic arm and monitoring multiple video streams for signs of danger. A system processing images at the speed of production can afford to drop only a small percentage of frames during inference.
The challenge of getting computer vision to work at the edge is rarely in training the initial detector. It’s about getting the model to run quickly enough on edge hardware inside an industrial enclosure without overheating the board and going over the power budget.
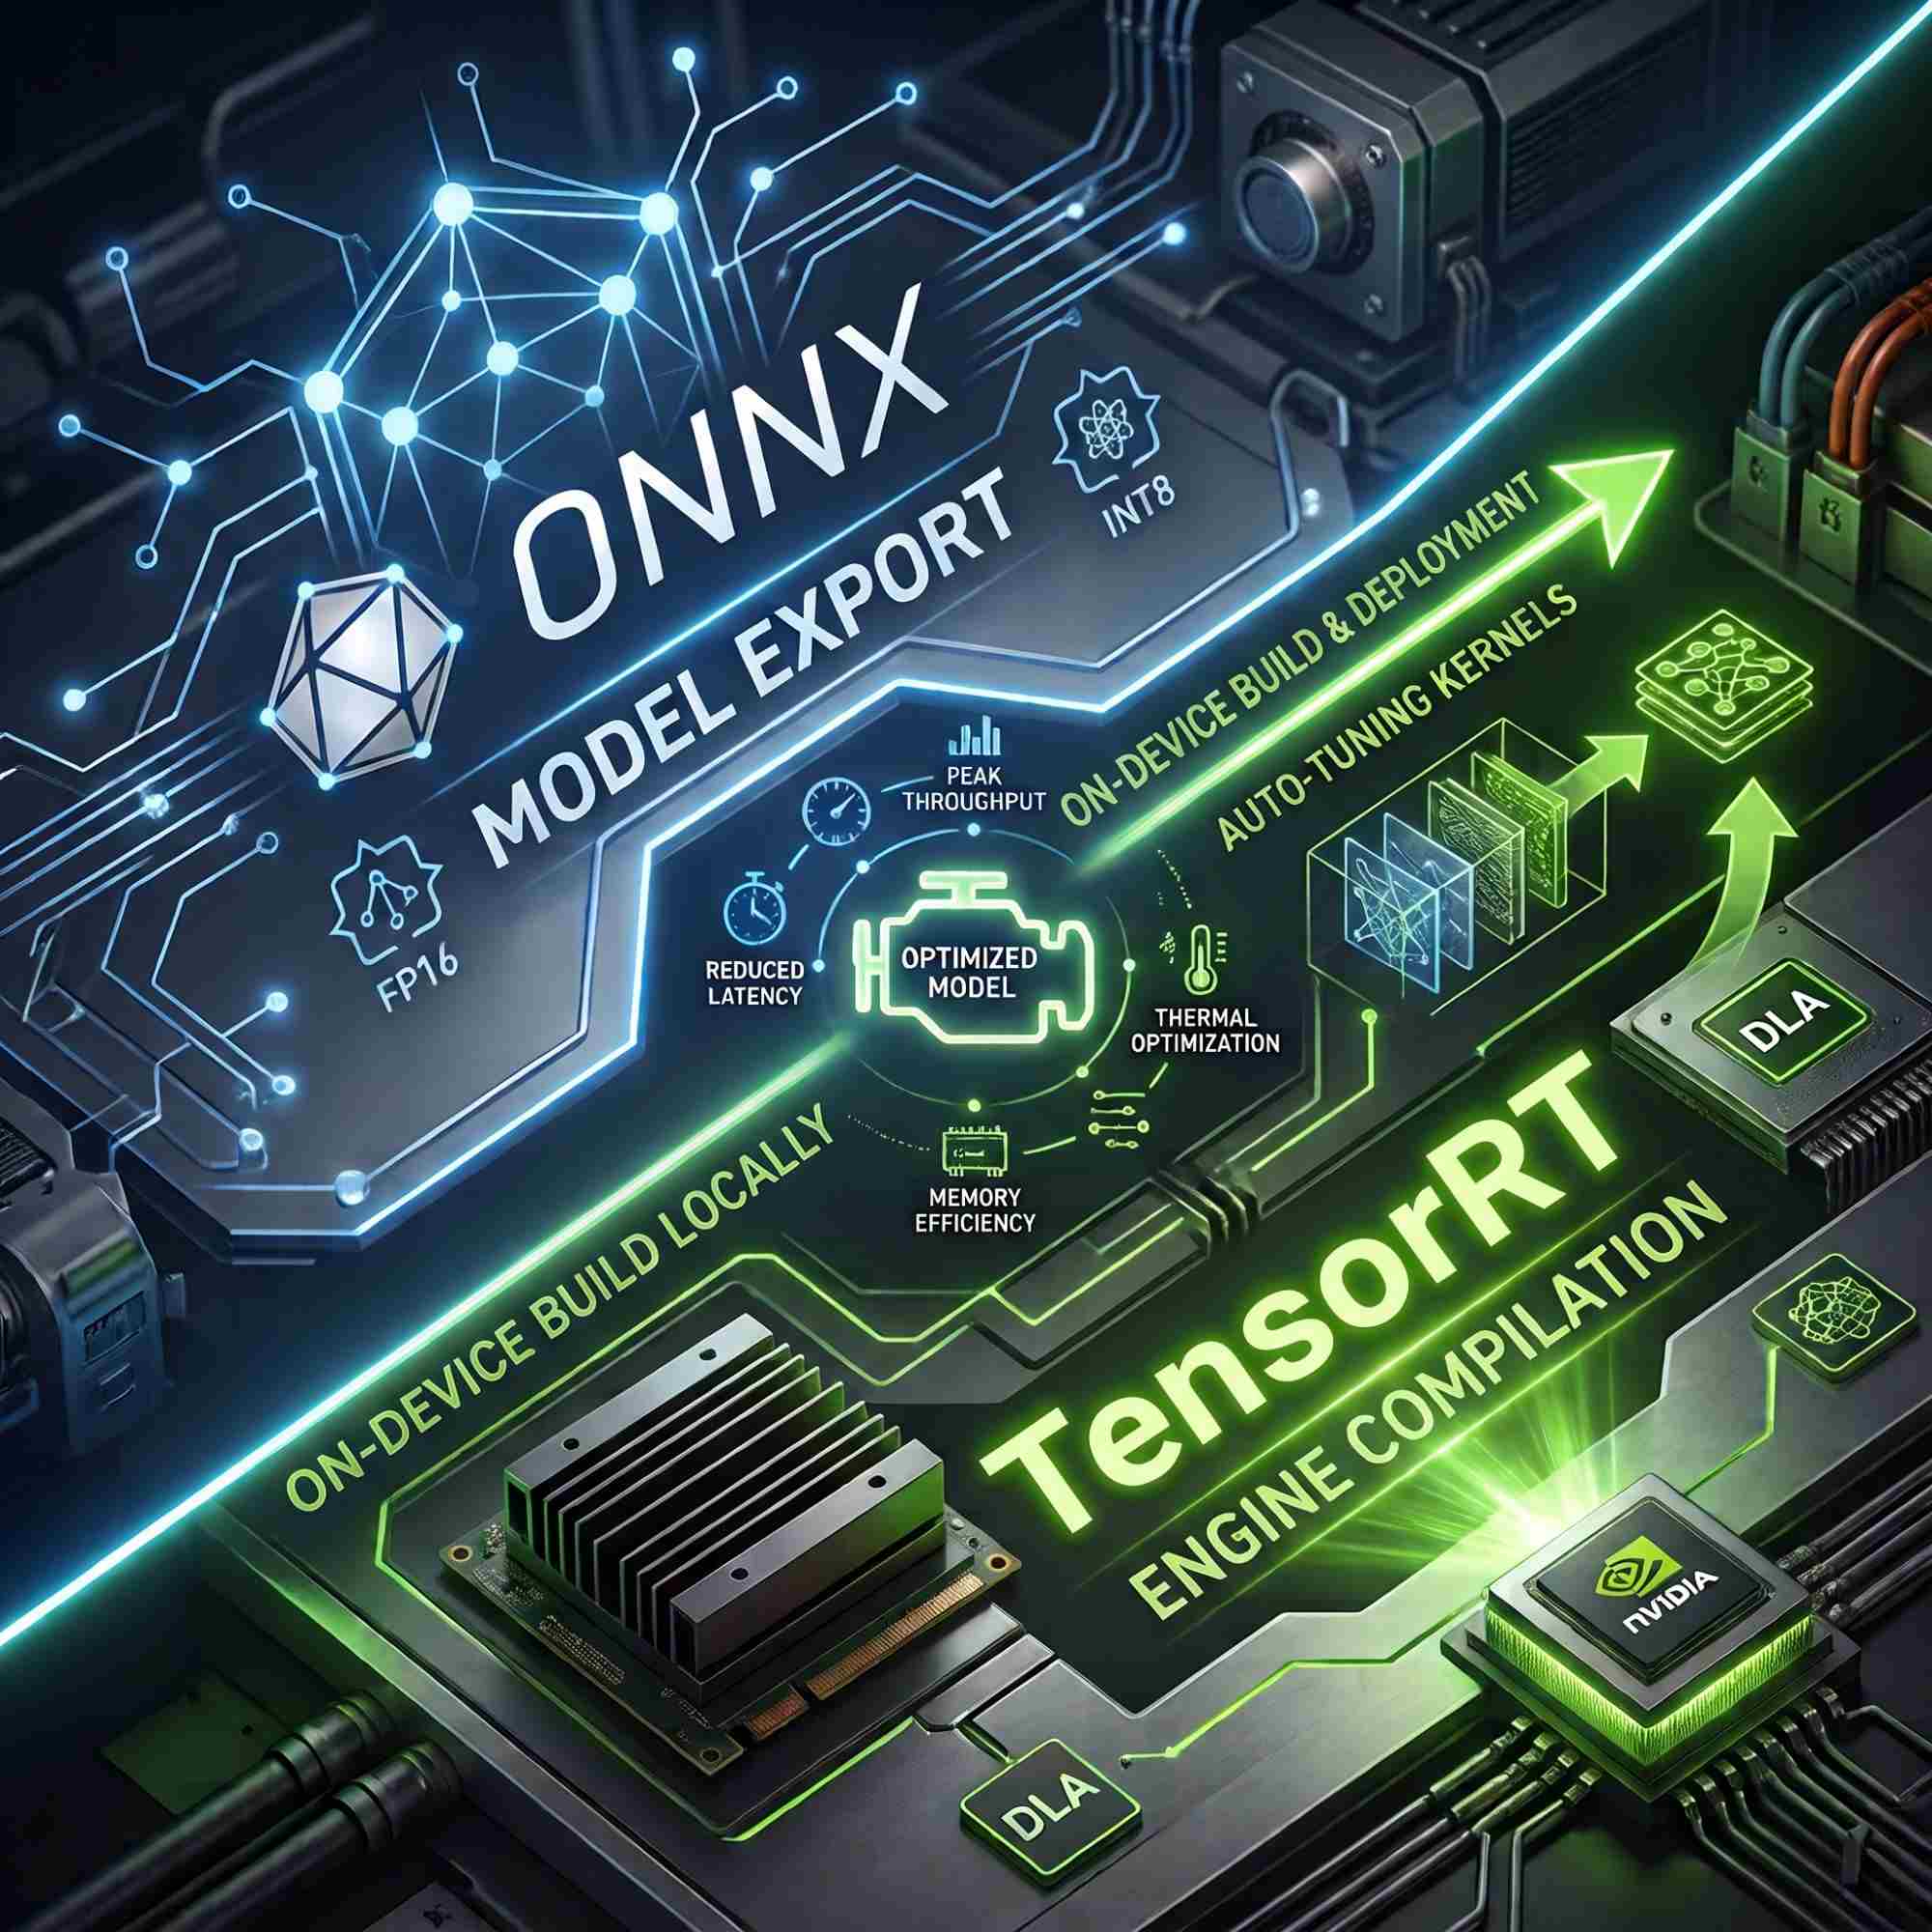
That’s where comparing ONNX vs TensorRT comes in handy. In this post, we will describe how we dealt with model export, engine compilation, and edge deployment on NVIDIA Jetson nodes and why shipping the portable ONNX file and compiling the TensorRT engine directly on each device is a reliable pattern for real-time edge vision.
ONNX vs TensorRT: They Are Not Really Competitors
Developers often treat this choice as an either-or rivalry, but they solve different steps in the deployment chain:
- ONNX (Open Neural Network Exchange): An open specification of a neural network, including layer types, shapes, and weights. An interchange format (not an execution engine).
- NVIDIA TensorRT: NVIDIA’s inference compiler and runtime. Takes a network graph (often from ONNX) as input, and compiles it into an optimized binary (engine) for execution.
- ONNX Runtime: General-purpose runtime for executing ONNX models on CPU or CUDA. Has an optional TensorRT execution provider that offloads subgraphs to TensorRT if they’re supported.
So what is the practical question here? Which runtime should our ONNX file execute on this particular device?
Why Generic Execution Is Often Not Enough on Embedded Hardware
New people on an edge vision project often ask me why we can’t just run ONNX Runtime with CUDA execution provider everywhere. It’s a good question, and it works out of the box. ONNX Runtime applies their own graph optimizations including some basic operator fusion, and they use tuned cuDNN and cuBLAS kernels.
On a small embedded GPU executing 24/7, however, the differences in the remaining architectural elements matter:
- TensorRT creates kernels optimized for the particular GPU architecture they run on, as opposed to generic ones.
- It has aggressive FP16 and INT8 execution paths that save memory (which is often the main limiting resource on these shared memory Jetson devices).
- It optimizes memory allocations to allow tensors that are never simultaneously active to share the same memory buffer.
In latency-critical applications, where a frame needs to be processed in a fraction of a second, computational headroom is crucial and our experience shows that a TensorRT FP16 engine provides an order of magnitude throughput and latency improvements over a well-optimized TensorFlow GPU inference application.
What ONNX Gives Us
When we train our object detection or instance segmentation model in PyTorch, the resulting file (.pt) is tied to PyTorch’s internals. Once you export your model to ONNX format, it becomes a hardware-agnostic representation understandable by many runtimes and accelerators.
import torch

def export_to_onnx(model, output_path: str = "active_model.onnx"):
    model.eval()  # export in inference mode
    dummy_input = torch.randn(1, 3, 640, 640, device="cuda")
    torch.onnx.export(
        model,
        dummy_input,
        output_path,
        export_params=True,
        opset_version=17,  # must be supported by the TensorRT version on the target
        do_constant_folding=True,
        input_names=["images"],
        output_names=["output"],
    )
    print(f"Exported ONNX graph to {output_path}")
The exported .onnx file is our universal build artifact. We save it in our model registry, track its hash, and push it out to the edge nodes no matter what their particular hardware revision happens to be.
What TensorRT Does Under the Hood
TensorRT works as an optimizing compiler, analyzing the entire network and generating a serialized engine (.engine) for a single GPU. The main optimization techniques of TensorRT are:
1. Layer Fusion
Chains of operations, such as Convolution → BatchNorm → Activation, can be fused into fewer GPU kernels to reduce kernel-launch overhead and avoid unnecessary intermediate transfers to and from global GPU memory. During inference, BatchNorm parameters are often folded into the preceding convolution when the model is exported in evaluation mode, and this fusion may already be represented at the ONNX level. However, additional fusion is still beneficial for operations such as activations, element-wise computations, and residual connections. Although ONNX Runtime performs several graph-level optimizations and fusions, TensorRT generally applies more aggressive, hardware-aware optimizations tailored to the target NVIDIA GPU.
2. Kernel Auto-Tuning
Similar operations, such as 3×3 convolution, can be implemented in a variety of ways, and TensorRT selects the fastest option during the build process by benchmarking the candidate kernels on the target GPU.
3. Reduced Precision
Most edge computer vision applications do not benefit from 32-bit precision; FP16 is often sufficient, reducing memory traffic by half while also taking advantage of Tensor Cores, and INT8 inference with proper calibration can provide higher throughput.
Always re-validate accuracy after lowering precision. Compare FP16 or INT8 outputs against the FP32 baseline on a representative validation dataset, paying close attention to small objects or rare edge cases where quantization noise can cause degradation.
4. Memory Reuse
Tensors that are never used at the same time can share the same memory buffer, reducing the overall memory footprint during inference, another critical consideration for embedded devices with small amounts of memory.
Why Engines Are Not Portable
A TensorRT engine is tied to
- the GPU architecture it was built for (e.g., Orin class vs. Xavier class GPU), and
- the TensorRT version (and thus JetPack release) it was built with.
An engine built with a workstation GPU will not load on a Jetson. Nor will it load on the same Jetson but with a different JetPack or TensorRT version. In general, engines built with newer versions of TensorRT will not load in older versions. This is true for all platforms, not just Jetsons.
ONNX Runtime vs TensorRT at a Glance
| Feature | ONNX Runtime (CUDA EP) | TensorRT engine |
|---|---|---|
| Startup | Immediate | Build once (minutes), fast load afterwards |
| Portability | Broad across platforms | Specific to GPU architecture and TensorRT version |
| Optimization | Graph optimizations, cuDNN and cuBLAS kernels | Hardware-aware fusion plus auto-tuned kernels |
| Precision options | FP32 / FP16 | FP32 / FP16 / INT8 |
| Best for | Flexibility, development fallback | Peak throughput and efficiency on NVIDIA hardware |
The Deployment Pattern: Ship ONNX, Build Locally
Because engines don’t cross GPU types or TensorRT versions, we don’t ship .engine files across the fleet; the pipeline ships the universal .onnx model from our registry and each edge node builds its own engine on the local machine.
This is not the only valid approach. You can also prebuild engines per device type and JetPack version in CI, or let DeepStream or ONNX Runtime’s TensorRT provider build and cache engines automatically. We prefer on-device builds because the engine always matches the local hardware and software environment.
Our bootstrap script checks whether an engine exists for the active model. If not, it calls trtexec:
#!/usr/bin/env bash
set -e

ONNX_MODEL="/opt/edge-inspection/models/active_model.onnx"
ENGINE_MODEL="/opt/edge-inspection/models/active_model.engine"
TIMING_CACHE="/opt/edge-inspection/models/timing.cache"

if [ ! -f "$ENGINE_MODEL" ]; then
    echo "No compiled engine found for this GPU. Building with trtexec..."
    /usr/src/tensorrt/bin/trtexec \
        --onnx="$ONNX_MODEL" \
        --saveEngine="$ENGINE_MODEL" \
        --fp16 \
        --memPoolSize=workspace:2048MiB \
        --timingCacheFile="$TIMING_CACHE"
    echo "TensorRT engine build complete."
fi
Running the Engine
We keep the inference loop lean and explicitly manage the CUDA buffers. In the example below, we target TensorRT 10+ which uses the tensor-address API (execute_async_v3) rather than the bindings-based execute_async_v2 binding API.
import ctypes
import numpy as np
import tensorrt as trt

_TRT_LOGGER = trt.Logger(trt.Logger.WARNING)
_cudart = ctypes.CDLL("libcudart.so")
_H2D, _D2H = 1, 2  # cudaMemcpyHostToDevice, cudaMemcpyDeviceToHost


def _check(err: int):
    if err != 0:
        raise RuntimeError(f"CUDA call failed with error code {err}")


def _pinned_array(shape, dtype):
    nbytes = int(np.prod(shape)) * np.dtype(dtype).itemsize
    ptr = ctypes.c_void_p()
    _check(_cudart.cudaMallocHost(ctypes.byref(ptr), ctypes.c_size_t(nbytes)))
    buf = (ctypes.c_byte * nbytes).from_address(ptr.value)
    return np.frombuffer(buf, dtype=dtype).reshape(shape), ptr


def _device_buffer(nbytes):
    ptr = ctypes.c_void_p()
    _check(_cudart.cudaMalloc(ctypes.byref(ptr), ctypes.c_size_t(nbytes)))
    return ptr


class JetsonInferenceSession:
    def __init__(self, engine_path: str, input_name="images", output_name="output"):
        with open(engine_path, "rb") as f:
            engine_data = f.read()

        runtime = trt.Runtime(_TRT_LOGGER)
        self.engine = runtime.deserialize_cuda_engine(engine_data)
        if self.engine is None:
            raise RuntimeError("Engine failed to load (wrong GPU or TensorRT version?)")
        self.context = self.engine.create_execution_context()

        self.input_name, self.output_name = input_name, output_name
        in_shape = tuple(self.engine.get_tensor_shape(input_name))
        out_shape = tuple(self.engine.get_tensor_shape(output_name))
        in_dtype = trt.nptype(self.engine.get_tensor_dtype(input_name))
        out_dtype = trt.nptype(self.engine.get_tensor_dtype(output_name))

        # Allocate once at startup: pinned host memory + device memory
        self.h_input, self._h_in_ptr = _pinned_array(in_shape, in_dtype)
        self.h_output, self._h_out_ptr = _pinned_array(out_shape, out_dtype)
        self.d_input = _device_buffer(self.h_input.nbytes)
        self.d_output = _device_buffer(self.h_output.nbytes)

        self.context.set_tensor_address(input_name, self.d_input.value)
        self.context.set_tensor_address(output_name, self.d_output.value)

        self._stream = ctypes.c_void_p()
        _check(_cudart.cudaStreamCreate(ctypes.byref(self._stream)))

    def run(self, frame: np.ndarray) -> np.ndarray:
        np.copyto(self.h_input, frame)  # stage into pinned memory

        _check(_cudart.cudaMemcpyAsync(
            self.d_input, self._h_in_ptr,
            ctypes.c_size_t(self.h_input.nbytes), _H2D, self._stream))

        if not self.context.execute_async_v3(stream_handle=self._stream.value):
            raise RuntimeError("TensorRT execution failed")

        _check(_cudart.cudaMemcpyAsync(
            self._h_out_ptr, self.d_output,
            ctypes.c_size_t(self.h_output.nbytes), _D2H, self._stream))

        _check(_cudart.cudaStreamSynchronize(self._stream))
        return self.h_output
What this buys us:
- Allocation of buffers once, not per frame, which allows for latency to be predictable.
- Pinned host memory allows for truly asynchronous copies. Regular NumPy arrays are allocated in pageable memory, which makes asynchronous copies impossible.
- Every call is checked for errors, making errors impossible to silently swallow.
FP16 and Tensor Core Alignment
Tensor Cores are most performant with channel dimensions which are multiples of 8 (16 for INT8), meaning that unusual channel counts such as 37 or 75 in a custom model backbone could cause TensorRT to pad these layers or use slower alternate implementations.
However, this is only one potential explanation for FP16 acceleration not providing the expected boost – the following also contribute to whether a model would see throughput gains from lower precision:
- Per-layer execution profiles: trtexec –loadEngine=active_model.engine –dumpProfile
- Time spent in video capture and decode, and CPU-side preprocessing
- Cost of non-maximum suppression and post-processing
- Whether the model is small enough to be launch-bound or memory-bound rather than compute-bound
In the majority of common modern vision model architectures, channel dimensions are already aligned to binary multiples and hence do not need to be adjusted – this consideration primarily affects custom model backbones.
Building a Production Fallback Chain
A successful production computer vision system must have a prioritized execution chain such that a missing engine or failed build does not cause a total failure of the system. The following fallback prioritization could be implemented:
- TensorRT engine: if /models/active_model.engine exists and loads cleanly, we can use it for real-time inference.
- Local build: if only active_model.onnx is present, we could execute trtexec and hot-swap the newly built engine in once it is ready. Ideally the build would be run outside the processing window, or on a separate node, to minimize contention with active camera processing threads for GPU memory.
- ONNX Runtime fallback: if a build fails, we could fall back to using the ONNX Runtime with the CUDA execution provider. Throughput will be lower, but the application can continue running.
- Passthrough mode: if all forms of hardware acceleration fail, the edge service should alert local telemetry, log the failure, and switch the camera feed to a raw passthrough mode so that operators can manually inspect the affected feed.
This allows the same software stack to run on development laptops, test benches, and production edge nodes with minimal or no code changes.
Things to Watch Out For
- Version compatibility: older JetPack releases ship older TensorRT versions that may not support newer ONNX opsets. Match your export opset to the target TensorRT version.
- Accuracy validation: re-test after FP16 or INT8 conversion on real-world test sets, including rare edge cases.
- Bigger levers: INT8 quantization and, on supported Jetson devices, the Deep Learning Accelerator (DLA) can give larger gains than FP16 alone.
- Fair comparisons: compare like with like. FP32 ONNX Runtime against FP16 TensorRT mostly measures the precision shift, not the runtime efficiency.
- Thermals and power modes: sustained 24/7 load behaves differently from a short benchmark. Test at your target deployment power mode inside a realistic enclosure.
Wrapping Up
Building a reliable edge vision system is rarely about squeezing out marginal accuracy gains on paper. It is about engineering an inference pipeline that runs deterministically inside real hardware and thermal constraints.
In the ONNX vs TensorRT workflow, each format serves a distinct purpose:
- Use ONNX as the universal interchange artifact that decouples model training and registry management from target hardware.
- Use TensorRT on NVIDIA edge nodes to get maximum throughput and thermal efficiency, building engines per device and per software version.
- Validate accuracy after lowering precision and measure end-to-end performance, not just model latency.
- Build a fallback chain so a failed optimization gracefully degrades service instead of crashing the system.
Pairing portable ONNX artifacts with on-device TensorRT builds and a robust fallback chain gives you clean versioning during development and the low-latency execution needed to run edge computer vision at full speed.
Ready to bring real-time AI to your edge infrastructure? See how edge AI runs on NVIDIA Jetson with low-latency inference and reliable OTA updates. To discuss your edge deployment requirements, book a technical demo with our team.